Observed flow, not idealized process
Real steps, handoffs, waits, roles, tools, and exceptions are captured.
Before a large investment, we test feasibility with a small and measurable experiment.
AI creates value when it meets real decisions, documents, waits, handoffs, and exceptions. We capture that operating flow first, then decide where AI, deterministic automation, or a considered hybrid is the credible answer.
Our first question is not “which model?” It is “which change must become measurable?”
Real steps, handoffs, waits, roles, tools, and exceptions are captured.
Representative samples, quality, access rights, and preparation cost are examined.
The baseline, acceptance measure, and post-pilot decision are framed early.
The outcome owner and the people expected to adopt the solution shape the test.
Choose an operating field to see common signals, credible opportunity candidates, and the first evidence needed for a useful test.
Look for points where experts spend time finding answers, triaging requests, or repeatedly passing a case between people.
First test: a bounded set of real questions and expert reference answers.
First test: historical requests, correct destination, and handling time.
A metric needs both a baseline and an accountable owner before pilot.
Opportunity appears where finding, comparing, or extracting information is slow and the ability to trace an answer back to evidence matters.
First test: a representative pack of standard and exceptional formats.
First test: real questions with verifiable reference answers.
An answer without provenance or a review path is not deployment-ready.
Analytics opportunities begin with a specific management question—not more charts or an isolated forecast without a decision owner.
First test: historical data, decision point, and cost of error.
First test: comparison with a simple baseline and current decision method.
A better model matters only if it enables a better decision.
Not every repetitive task needs AI. Integration and explicit rules can be faster, safer, and more dependable than an intelligent model.
First test: workflow map, rules, and examples of exceptions.
First test: approved tools, authority boundary, and human checkpoints.
The aim is not to remove people; it is to remove low-value repetition.
Each output should reduce a specific uncertainty. When evidence is weak, stopping or redesigning is a valid result—not a failed project.
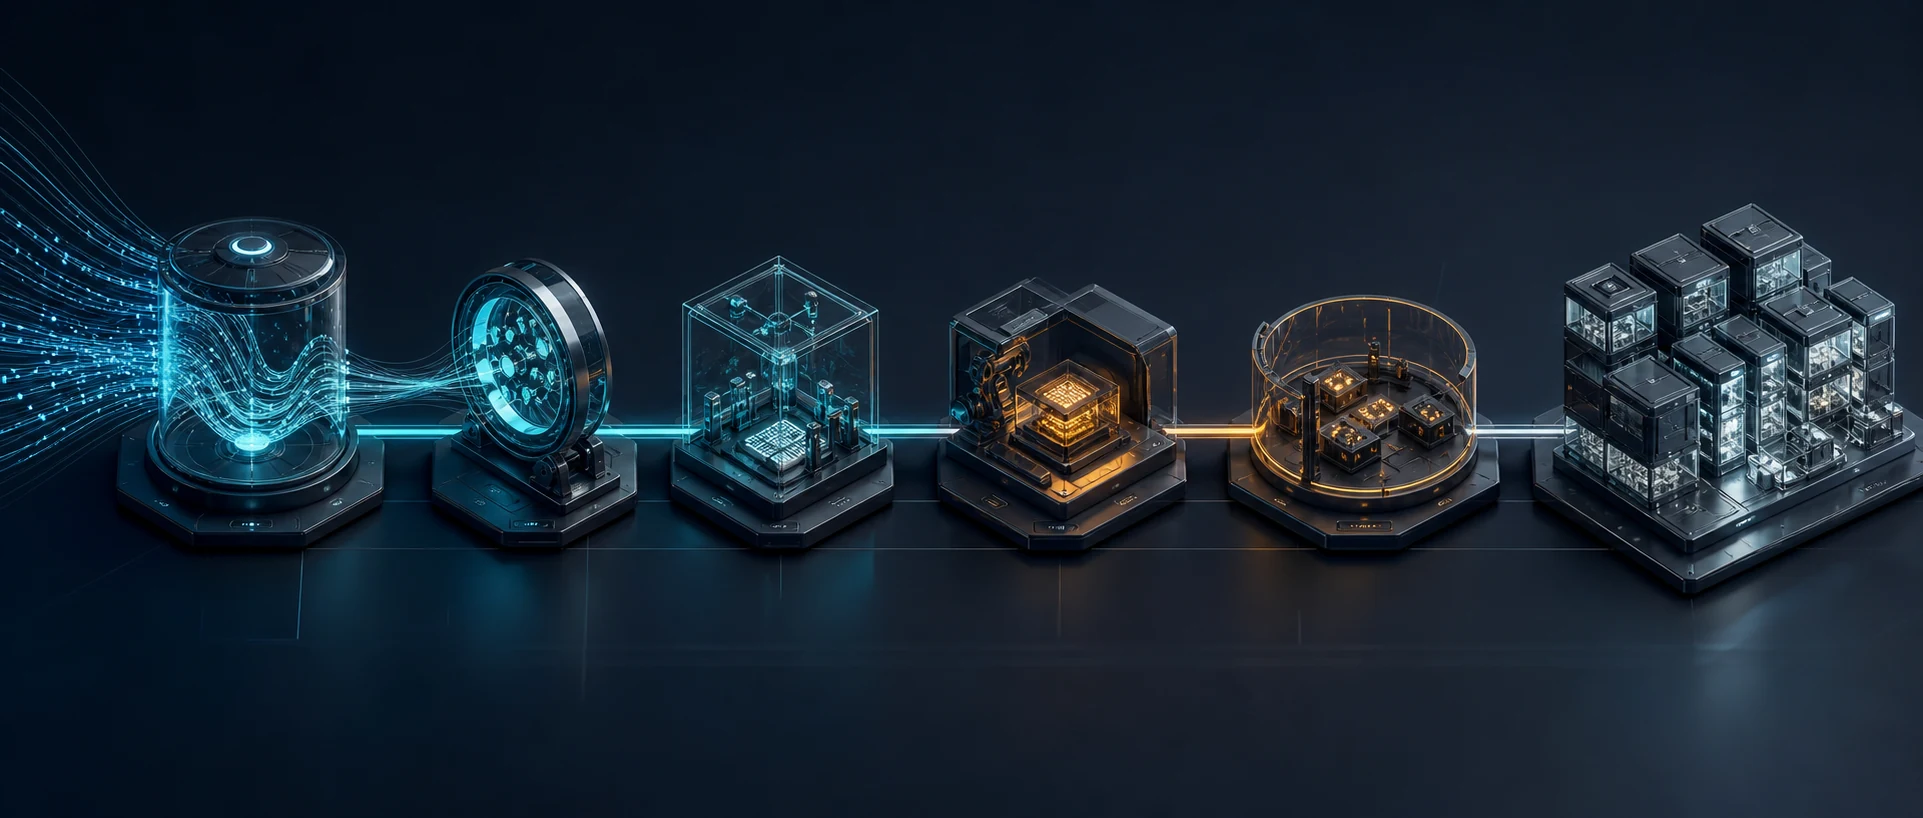
Real work, roles, tools, handoffs, and friction.
Candidates, value, dependencies, and test priority.
Data, quality, security, integration, and limits.
Test the highest-risk value or technical assumption.
Real users, a clear boundary, and acceptance criteria.
Durable architecture, deployment, monitoring, improvement.
Select the criteria for which you already have early evidence. This exposes conversation gaps; it does not replace a professional assessment.
The exact package follows the engagement stage, but the intent stays constant: clarify what is worth building, how it should be tested, and what move comes next.
Explore AI & Data CapabilitiesCandidates, value, readiness, risk, and dependencies.
Boundary, baseline, owner, and decision question.
Findings across data, technology, security, and operations.
A bounded slice focused on the riskiest assumption.
Acceptance criteria, results, limits, and learning.
Architecture, phases, monitoring, and ownership.
You do not need to name a model or platform. The current flow, its main friction, and the change you want to see are enough for the first conversation.